
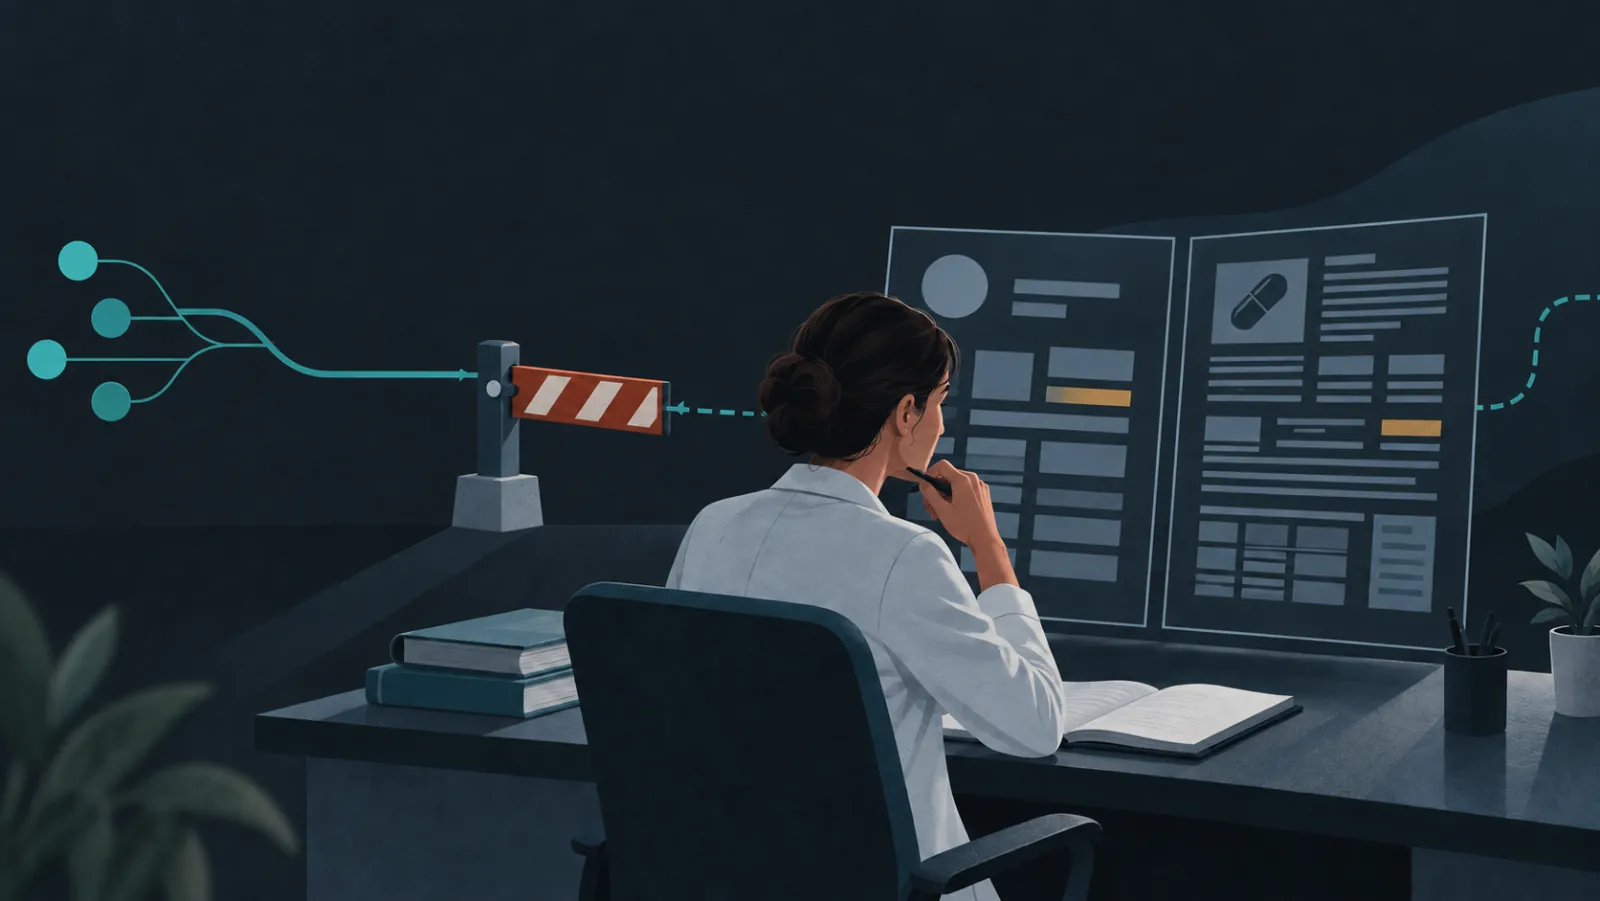
Consider a hypothetical pharmacovigilance workflow. An artificial intelligence (AI) system drafts an adverse-event narrative. A qualified reviewer opens it, checks that it reads sensibly, and clicks “Approve.” The record captures the reviewer’s identity, the time, and the approved version. Every required field is complete.
The source report, however, describes a sequence of events that the draft has reversed. Detecting that error requires comparison with the original. The reviewer sees only the draft; the source sits in another application, access requires a separate request, and the queue is already behind schedule. The approval is authentic. The claimed safeguard is unsupported.
Meaningful human oversight is the capacity to reach an informed judgment about an AI-assisted decision and exercise that judgment at a point when it can still protect the intended outcome. It is a property of the working arrangement: the person, the technology, the evidence, the process, and the organization that provides them. A name beside a decision establishes who approved it. It does not establish that the conditions for review existed.
Start with the Decision the Review Is Meant to Protect
An oversight design starts with a specific decision and a plausible failure. A reviewer checking a generated narrative needs to detect unsupported statements, omissions, and changes in meaning. A reviewer assessing a manufacturing recommendation needs to judge it against process conditions and acceptance criteria. A reviewer examining a clinical screening result needs the relevant record and protocol criteria. “Check the AI output” defines none of this work.
The process owner should specify what is being reviewed, against which evidence and standard, by whom, and with what possible dispositions. The depth and independence of review should follow the consequence of error, the model’s influence, and the strength of other controls. These are design judgments for the particular use, rather than a universal requirement to reread every output with equal intensity.
Timing is part of the control. In a human-in-the-loop arrangement, the relevant action waits for a person’s decision. In a human-on-the-loop arrangement, the system acts while a person supervises and can intervene. The latter offers protection only where detection and intervention are feasible at the system’s speed and volume. A stop control offers little protection against an irreversible action completed before the supervisor could notice it. Retrospective review may identify and correct a problem, but it protects later cases, not the one already acted on.
Coverage also needs an honest boundary. A system may send flagged cases to reviewers while allowing other cases to proceed automatically. The separate problem of how review varies across consequential routes is developed in Human Presence Does Not Propagate (Evgrafov 2026), with a practical account in “What ‘Human in the Loop’ Doesn’t Tell You”. Effective review of the cases a person receives does not establish control over the cases they never see.
Technology Has to Make Verification Possible
The reviewer’s interface determines which questions can realistically be asked. If it presents a polished conclusion and an approval button, it supports acceptance. To support verification, it needs to make the basis of the conclusion accessible within the review workflow.
Depending on the decision, that basis includes the original input, source documents, relevant prior records, the applicable procedure or acceptance criteria, and the proposed changes. The reviewer also needs to recognize AI-generated content, distinguish it from human-entered material, and identify the system version or configuration relevant to its limitations. Missing inputs, failed retrievals, stale source material, and conditions outside the approved use should be visible where they affect the judgment.
Access means usable access at the point of work. A reviewer who technically has permission to retrieve a record but needs several applications, an unavailable colleague, or a support ticket to reach it has a weaker control than the permission list suggests. Side-by-side comparison, links to the actual supporting passages, clear change displays, and navigation back to the underlying record can make substantive checking practicable. Access should remain appropriate to the role and the information needed for the decision.
The evidence should permit a check that is sufficiently independent of the model’s conclusion. An explanation generated by the same model is another output to assess. It may help a reviewer understand a proposal, but it does not establish that the proposal is correct. Similarly, checking every document an AI search retrieved cannot establish that it retrieved every relevant document. A conclusion about absence or completeness needs a way to examine what may have been omitted.
Confidence displays need similar care. A score is useful only when its meaning, limitations, and relationship to observed performance are understood for the use in question. Fluent wording, an authoritative layout, or a confident explanation should not be allowed to stand in for evidence. Reviewers need to know when uncertainty cannot be estimated reliably, as well as when the system reports it.
The U.S. Food and Drug Administration (FDA), Health Canada, and the UK’s Medicines and Healthcare products Regulatory Agency (MHRA) jointly published transparency principles that emphasize information suited to users and workflows, known limitations, timely communication, and the performance of the human-AI team (FDA, Health Canada, and MHRA 2024). These are principles for machine-learning-enabled medical devices; applying that design logic to other GxP review workflows is a practical extension, not a claim that the device principles impose requirements on every AI system.
Education, Training, and Demonstrated Competence Do Different Work
The starting qualification belongs to the decision. Pharmacovigilance judgment requires the relevant clinical and safety expertise; a manufacturing decision requires the appropriate process and quality knowledge. Familiarity with an AI application cannot replace that foundation.
Education then supplies a working understanding of AI assistance: why an apparently plausible answer may be unsupported, why aggregate accuracy does not guarantee correctness in an individual case, how performance can vary across inputs and populations, and how reliance on automated advice can distort judgment. The aim is practical AI literacy appropriate to the role. A reviewer need not become a model developer to understand when reliance is poorly supported.
Training makes that understanding specific to the deployed system. It should address known failure modes, weaker source types or languages, input-quality limitations, uncertainty signals, exclusions from use, and the actions available when a case cannot be resolved. A narrative reviewer should practice identifying an omitted event or changed chronology if those are credible failures. Training should show how to verify, modify, reject, hold, and escalate an output, including partial disagreement with an otherwise useful result.
Competence is demonstrated by performance on representative and difficult cases. Attendance and course completion establish participation. Case-based assessment shows whether the person can recognize a problem, obtain the evidence needed, and make an appropriate disposition. Authorization to perform consequential review should reflect that demonstrated competence, with reassessment when the role or system changes and periodically according to risk.
For a purchased system, limitation knowledge has to cross the supplier boundary. Capability demonstrations and product brochures are inadequate training sources on their own. The organization needs evaluation findings, relevant limitations, and change information that can be translated into local training. Managers and process owners also need enough understanding to resource the control and interpret its performance; otherwise, trained reviewers operate inside an uninformed process.
Time and Attention Are Resources the Control Consumes
Human review takes work. That work includes opening sources, comparing information, resolving ambiguity, documenting material decisions, and obtaining specialist advice. An efficiency estimate that counts only the approval click omits the activity that makes the approval valuable.
Capacity planning should compare the expected volume and complexity of cases with the qualified reviewer time actually available. It should account for peak demand, difficult cases, leave, shift coverage, competing duties, and escalation. Increasing AI throughput can increase the review burden even when generating each output becomes cheaper. The operating model needs a response when the queue exceeds the capacity for substantive review: additional qualified support, restricted use, controlled prioritization, or another justified arrangement.
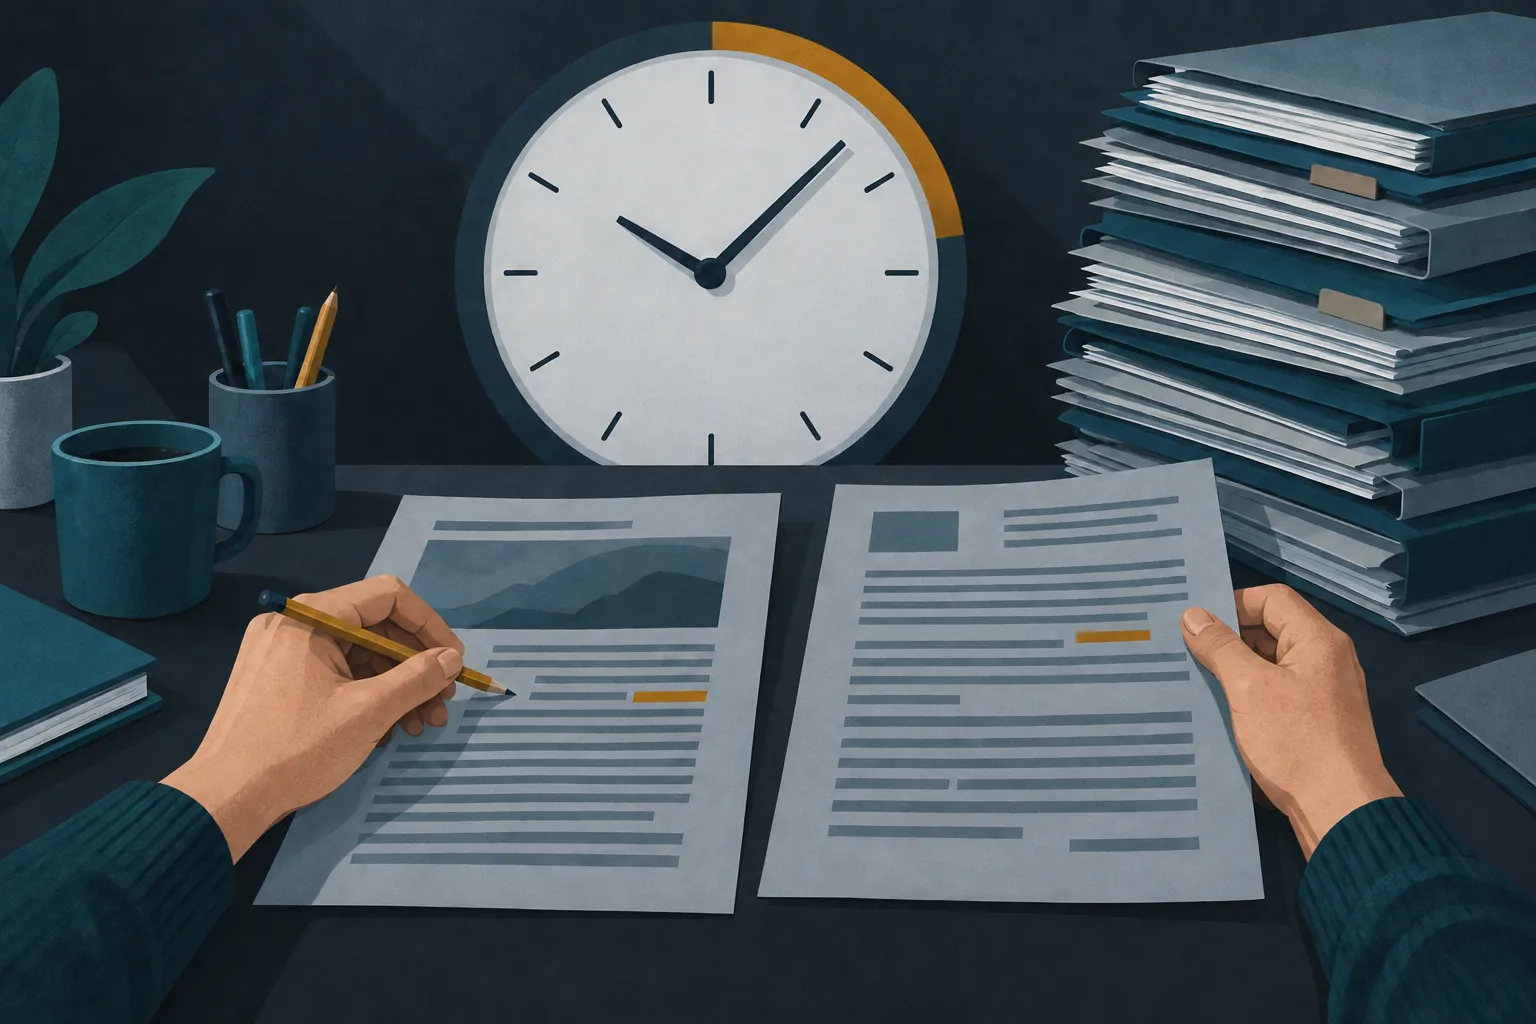
The review queue can grow faster than the time available to examine it. Capacity needs to be planned around substantive checking, including the difficult cases.
Time data can expose an implausible design, but they require interpretation. A screen-open interval includes time spent elsewhere. Adjacent approval timestamps may reflect batch recording rather than when each case was examined. Comparing total qualified hours with case volume can test whether the assumed average effort was feasible, provided all contributing reviewers and working time are counted. None of these measures proves that a particular case received attention.
A mandatory waiting period would not resolve that problem. Elapsed time is not a substitute for review. The stronger question is whether the allocated time is sufficient for the defined task and whether observation and outcome evidence show that the task is being performed.
Authority Needs a Working Process Behind It
A reviewer’s authority should be visible in what the system permits. Where the oversight design calls for it, the reviewer needs to be able to prevent an action, request more information, correct part of an output, reject a recommendation, escalate uncertainty, or stop further use. These actions should work through the interfaces and downstream systems that actually carry the decision into effect.
The procedure then has to support those choices. Escalation criteria should identify recognizable situations, such as conflicting source evidence, an input outside the approved scope, or an unresolved discrepancy with potential safety consequences. The escalation needs a recipient, an expected response, a disposition, and a record of resolution. The process should state what happens to the affected case while advice is pending and what fallback is available if the system or its evidence sources cannot be relied upon.
That fallback needs people, access, and capacity of its own. “Revert to manual review” is incomplete if no qualified staff can handle the volume or the original records are inaccessible. Where the intended control cannot operate, the organization needs to constrain or suspend the affected use, or establish another justified control. Keeping the approval field does not preserve the safeguard.
Organizational incentives can undo formal authority. If acceptance takes one click while every disagreement triggers disproportionate paperwork, the workflow encourages agreement. If managers treat overrides as evidence of an obstructive reviewer or measure performance solely through clearance rates, the organization discourages the judgment it claims to require. Appropriate documentation of a consequential decision remains necessary, but the burden should follow risk rather than whether the reviewer agreed with the model.
The decision record should distinguish acceptance, modification, rejection, and escalation. It should preserve the relevant output, source references, reviewer, timing, disposition, and material reasoning well enough to reconstruct the decision. An attributable approval trail is necessary evidence of what occurred; assessing the substance of the review requires more.
Design for Human Limitations
Even a knowledgeable, well-equipped reviewer can overrely on automated advice, a tendency known as automation bias. In a simulated prescribing study with 26 general practitioners, decision support improved their overall accuracy while also causing some initially correct decisions to become incorrect after advice was shown (Goddard, Roudsari, and Wyatt 2014). Those findings show that overall benefit and harmful deference can coexist; they do not supply a universal error rate for other workflows.
The practical response should reach beyond a reminder to remain vigilant. The organization should examine how the interface directs attention, whether reviewers can form a view from source evidence, and whether the process rewards scrutiny. Alert fatigue deserves attention too: repeated low-value warnings can encourage routine clearance of a queue that also contains consequential ones. Where appropriate, an initial assessment made before seeing the recommendation can be tested as a way to reduce anchoring. Such measures need evaluation in the actual task; adding steps indiscriminately can also consume attention.
This is another reason to avoid equating oversight with universal checking. Review should be concentrated where it can change a consequential outcome, with suitable verification and monitoring elsewhere. The allocation needs justification from risk and evidence. A process that requires exhaustive review at a volume no one can sustain creates the conditions for routine approval.
Establish Whether the Review Actually Works
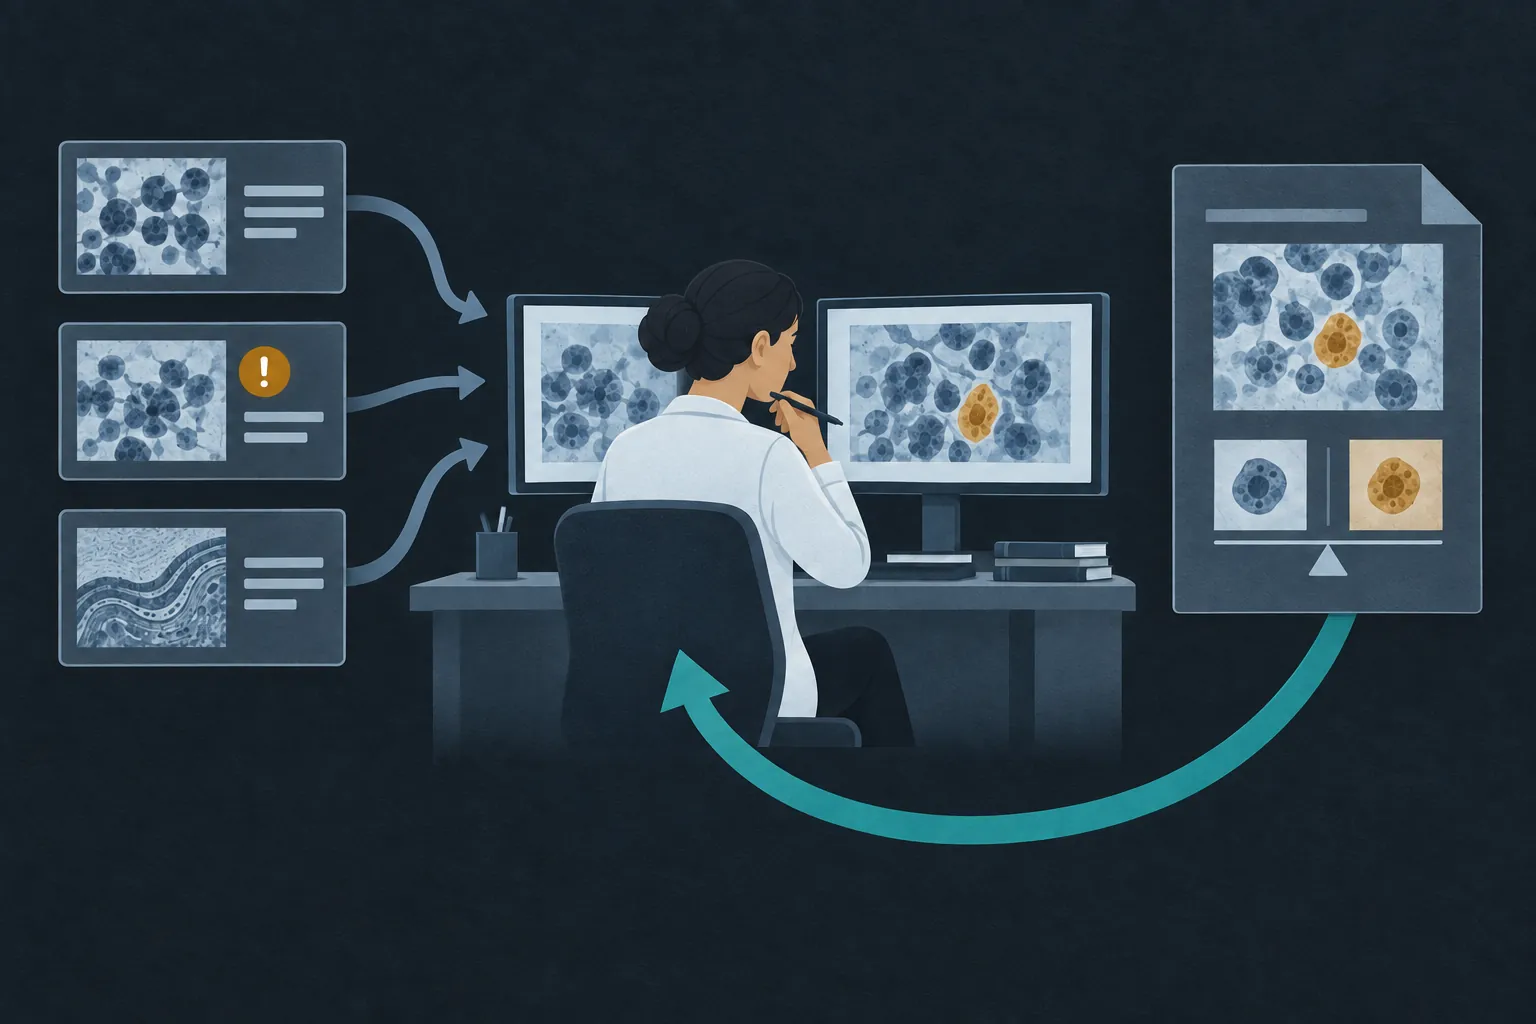
Oversight becomes demonstrable when realistic challenges and independent assessment show what the reviewer catches, what is missed, and what the organization changes in response.
If a risk assessment relies on human review, evaluation should test the combined process. Suitable challenges include plausible but wrong outputs, omitted information, ambiguous cases, degraded inputs, and correct outputs that should remain unchanged. The question is whether the model, interface, evidence access, reviewer, and procedure together achieve the required decision quality under realistic working conditions.
Useful methods include observation of routine review, independent rereview of a representative sample, and governed exercises using known errors or borderline cases. Challenge exercises should have an approved design, an appropriate reference judgment, and controls that keep test content from entering regulated records or causing operational action. Reviewers should know that such exercises form part of competency and control assessment without being told which specific case contains an error.
The assessment should examine missed errors and unnecessary human changes as well as successful corrections. It should also compare the combined workflow with the relevant baseline, which may include unaided review and model performance alone, and examine differences by case difficulty, input type, reviewer experience, site, relevant population, and system version where those differences could conceal failure. Agreement between a reviewer and a model is weak evidence if both relied on the same incomplete information.
Override rates, review times, and escalation counts are signals to investigate. A low override rate can reflect accurate outputs or uncritical acceptance. A high rate can reflect useful correction, poor model performance, or human error. Independent adjudication, and reliable downstream outcomes where available, help distinguish these explanations. No target approval time or override quota can establish meaningful oversight.
The evidence also needs a response. Recurrent corrections and near misses should reach the people responsible for investigation, monitoring, training, and change. Correcting one record may protect that case while leaving the same failure in many others. Human corrections should themselves be assessed before being treated as reference labels or fed back into model improvement.
Oversight Has to Survive Change
The arrangement that worked at release may cease to work after a model update, a changed prompt, a new source collection, a revised threshold, a different population, or an increase in volume. A supplier update can change characteristic errors and review demand while the local procedure remains untouched.
Change assessment should therefore revisit what reviewers see, what they have been trained to recognize, how much work reaches them, and whether their intervention remains effective. Material changes should reach the relevant users and oversight functions before they rely on the changed behavior. A vendor’s general statement that its platform is human-reviewed cannot establish the adequacy of a customer’s particular configuration and staffing.
Continued assurance connects competency assessment, review-quality evaluation, incident learning, and monitoring to named owners and defined actions. When the evidence shows that oversight has weakened, those owners need to decide whether to improve the interface, change staffing or training, narrow the use, strengthen another control, or stop the affected activity.
The reviewer remains answerable for the judgment they exercise. The organization remains answerable for the conditions that make that judgment possible, and for the system and process it authorized. Assigning a signature cannot transfer responsibility for inadequate information, impossible workloads, or an intervention mechanism that does not work.
The practical test is concrete: Faced with a consequential error, could this reviewer recognize the problem, reach the necessary evidence, make an informed decision, and change what happens in time? Then comes the evidentiary test: Has the organization shown that this occurs in practice? Meaningful human oversight requires both answers.
References
Evgrafov, George. 2026. Human Presence Does Not Propagate: Asymmetric Human Oversight and Verification in AI Decision Systems. Preprint. Zenodo. DOI.
Goddard, Kate, Abdul Roudsari, and Jeremy C. Wyatt. 2014. “Automation Bias: Empirical Results Assessing Influencing Factors.” International Journal of Medical Informatics 83 (5): 368–75. Article record. DOI.
QA4Tech. 2026. “What ‘Human in the Loop’ Doesn’t Tell You.” 8 September 2026. Article.
U.S. Food and Drug Administration, Health Canada, and Medicines and Healthcare products Regulatory Agency. 2024. “Transparency for Machine Learning-Enabled Medical Devices: Guiding Principles.” June 2024. Joint principles.